GLM-5.3-Flash-UD-Q4_K_XL-00001-of-00006.gguf
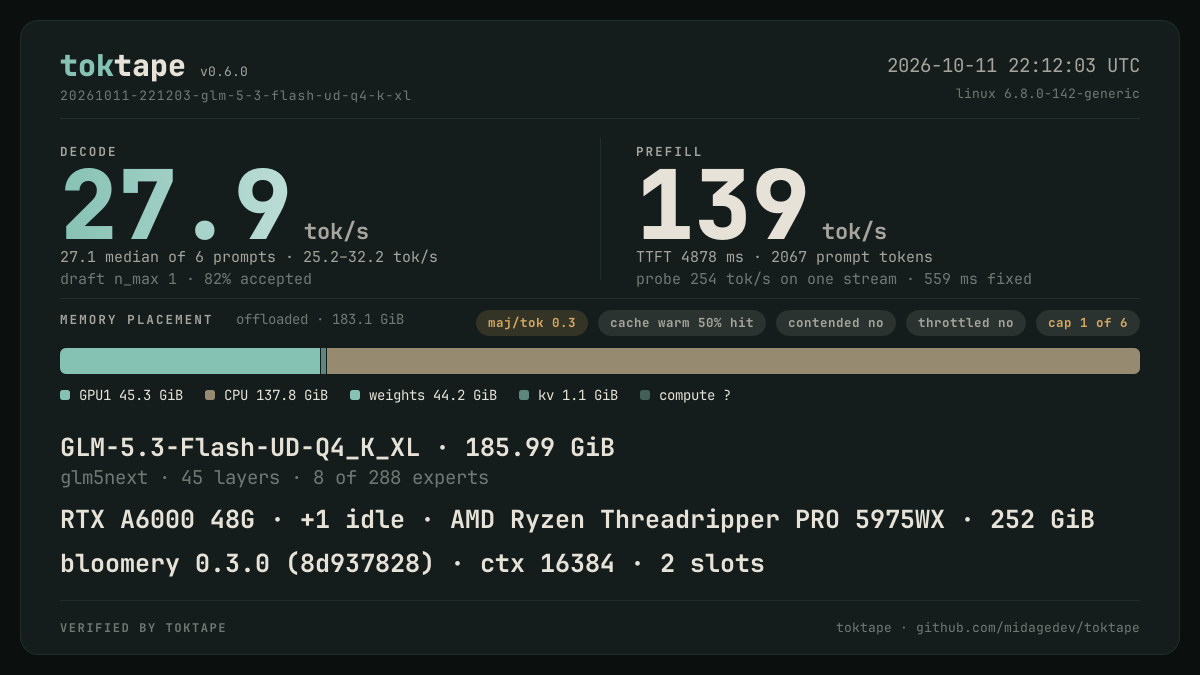
27.9 tok/s decode · 1 stream · q4_K · rtx-a6000
bloomery 0.3.0 prompt cache, the 0.3.0 arm. GLM-5.3-Flash UD-Q4_K_XL on the RTX A6000 alone (pinned by UUID; the 3090 in RIG was idle), serving defaults, greedy, thinking off. Six rounds, texts A A B C A A, one session; round 5 comes back to text A after B and C took both slots. 0.3.0 restores 2048 of round 5's 2066 prompt tokens from the host cache: first token 0.44 s. The 0.2.10 arm of the same rounds (round 5 cold, 9.09 s): https://tape.midagedev.com/r/qzxmypw7kug2qc7e65pd
| model | GLM-5.3-Flash-UD-Q4_K_XL-00001-of-00006.gguf |
| quantisation | q4_K · 4.5 bit |
| size | 199.7 GB · MoE 288/8 |
| engine | bloomery 0.3.0 (8d937828) |
| host | linux · 1x rtx-a6000 |
| gpus | NVIDIA RTX A6000 |
| streams | 1 |
| workload | 2067 in / 159 out · min 84 · 28 thinking · cache 50% |
| context | 16384 window · 2 slots |
| config | offload partial |
| draft | GLM-5.3-Flash-UD-Q4_K_XL-00001-of-00006.gguf · 82% accepted |
| machine | 293.8 of 550 W |
| prompt set | not in a comparison set |
| recorded | 2026-10-11T22:12:03Z |
| toktape | v0.6.0 |
Details
The transcript, the card as text, and why each caveat fired — read out of the record in your browser, the same way Replay draws it.
cold_cache, client_disagrees_with_server, thinking_ignored. The card that comes with this record spells each one out.Page views are counted with Cloudflare Web Analytics: no cookies, no fingerprinting. The toktape binary itself sends nothing anywhere.