0:00 / 0:00
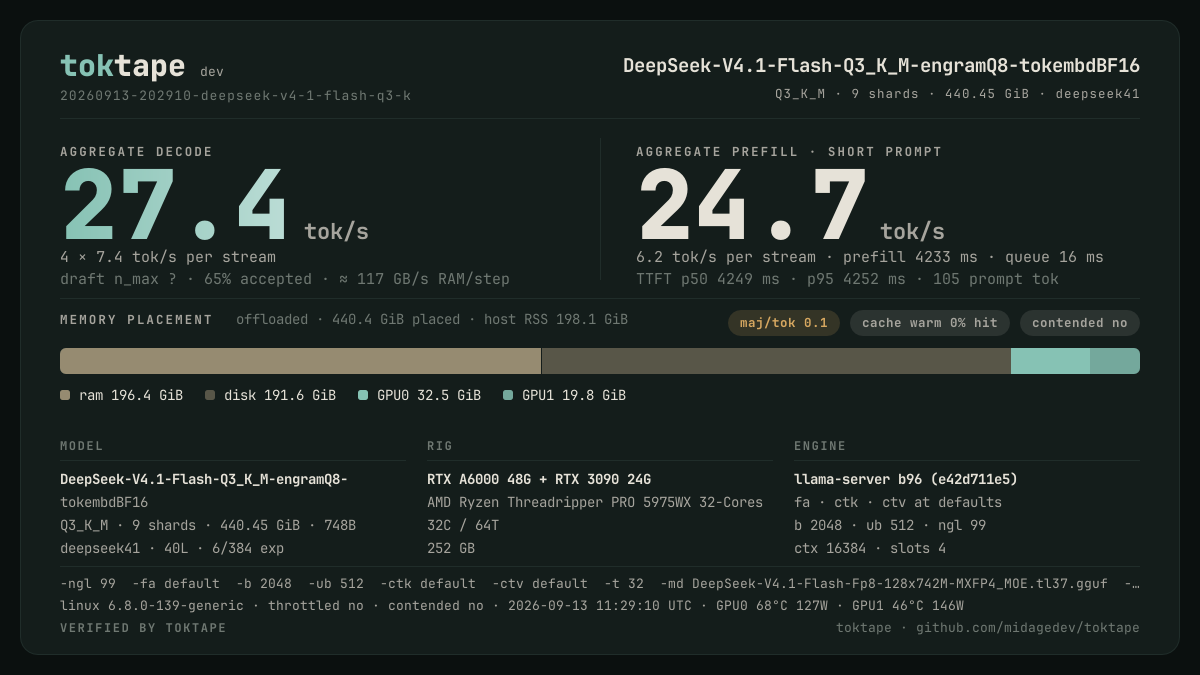
DeepSeek-V4.1-Flash Q3_K_M · 4 streams
DeepSeek-V4.1-Flash-Q3_K_M-00001-of-00009.gguf · 27.4 tok/s decode · 4 streams · Q3_K_M
DeepSeek-V4.1-Flash Q3_K_M (engram Q8, token embeddings BF16), 9 shards, ~347 GB — far more than the 72 GB of VRAM on the RTX A6000 + RTX 3090, so most of the experts stream from 252 GB of DDR4. llama-server b96.
Four streams: per-stream decode drops to ~7 tok/s but the aggregate is a touch above the single stream — the expert traffic from RAM is shared across streams.
decode
27.4tok/s
prefill
24.7tok/s
ttft p50
4249ms
| model | DeepSeek-V4.1-Flash-Q3_K_M-00001-of-00009.gguf |
| quantisation | Q3_K_M |
| engine | llama-server b96 |
| host | linux |
| gpus | NVIDIA RTX A6000 / NVIDIA GeForce RTX 3090 |
| streams | 4 |
| prompt set | not in a comparison set |
| recorded | 2026-09-13T20:29:10+09:00 |
| toktape | dev |
Details
The transcript, the card as text, and why each caveat fired — read out of the record in your browser, the same way Replay draws it.
! 1 caveat —
short_prompt_for_prefill. The card that comes with this record spells each one out.