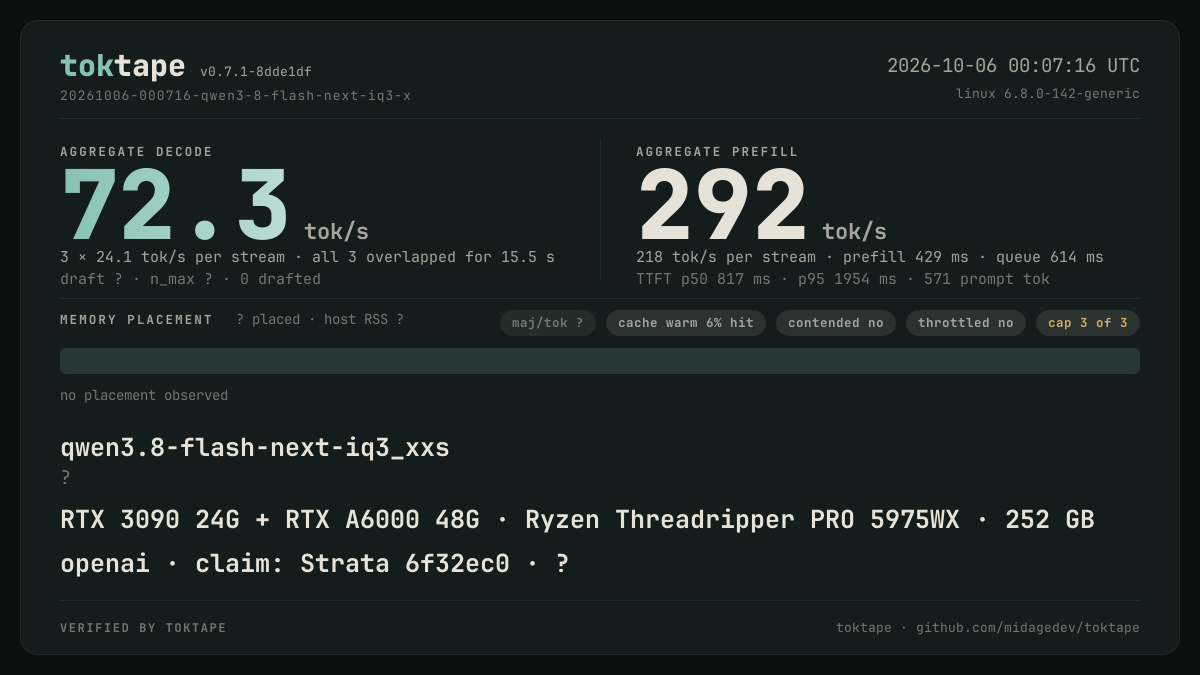
One RTX 3090 · Strata 6f32ec0 · Qwen3.8 Flash Next IQ3_XXS 76 GB · 3 streams (client-timed)
qwen3.8-flash-next-iq3_xxs · 69.5 tok/s decode · 3 streams
One RTX 3090 (250 W cap) on one box, one server at a time. The A6000 held nothing while each server was up; the script checked this. Same prompts for every engine: greedy, thinking off, one discarded warm-up per load. Recorded with toktape 0.7.1-8dde1df, which counts a server's child processes as the server.
Three setups: - bloomery 0.2.1 (commit b83f1269) on UD-Q4_K_XL (111 GB), at its defaults: MTP draft and adaptive residency. - Strata 6f32ec0 on its recommended GSQ-RCO IQ3_XXS file (76 GB). - Strata 6f32ec0 on the same UD-Q4_K_XL file bloomery serves. Strata reads it through --gguf-dir and lists that path as experimental.
Each setup ran once at one request (bloomery --parallel 1, Strata's setup config) for the one-stream tapes, and once at three (--parallel 3, or "parallel": 3 added to the config) for the three-stream tape.
The three-stream tapes are client-timed (--engine-kind openai), because Strata's /props reports total_slots 1 under "parallel": 3 (fix proposed upstream, Niko1221/Strata#1004).
Demonstration clips, not lease numbers.
| model | qwen3.8-flash-next-iq3_xxs |
| quantisation | ? |
| size | ? |
| engine | openai |
| host | linux |
| gpus | NVIDIA GeForce RTX 3090 / NVIDIA RTX A6000 |
| streams | 3 |
| workload | 202 in / 400 out · cache 6% · per stream |
| context | ? |
| config | ? |
| machine | 268.3 of 550 W |
| prompt set | not in a comparison set |
| recorded | 2026-10-06T00:07:16Z |
| toktape | 0.7.1-8dde1df |
Details
The transcript, the card as text, and why each caveat fired — read out of the record in your browser, the same way Replay draws it.
ragged_aggregate, client_disagrees_with_server, recorded, no_proc_view. The card that comes with this record spells each one out.Page views are counted with Cloudflare Web Analytics: no cookies, no fingerprinting. The toktape binary itself sends nothing anywhere.