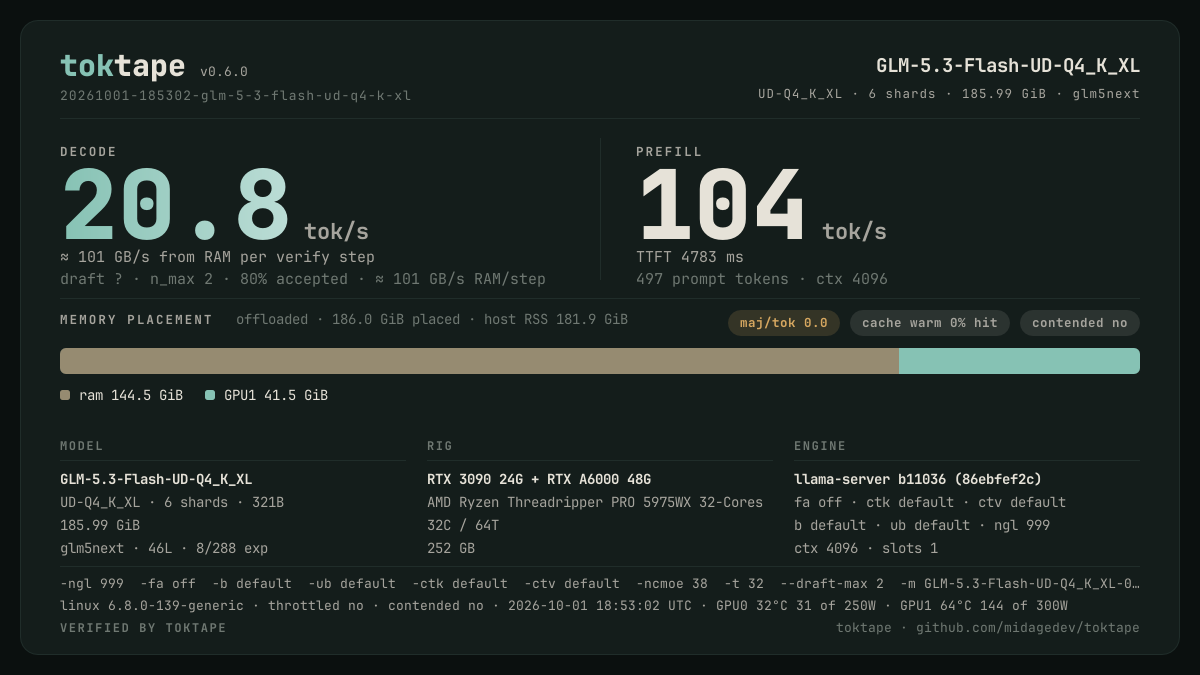
llama.cpp · GLM-5.3-Flash UD-Q4_K_XL · A6000 alone · coding review 497 in / 2000 out · PR #27754 MTP draft, -ncmoe 38
GLM-5.3-Flash-UD-Q4_K_XL-00001-of-00006.gguf · 20.8 tok/s decode · 1 stream · UD-Q4_K_XL
llama.cpp PR #27754 llama-server (86ebfef2c) on the A6000 alone: -ngl 999 --n-cpu-moe 38 -fa off -t 32 -fit off --no-op-offload -np 1 -ctxcp 0 --cache-ram 0 --spec-type draft-mtp --spec-draft-n-max 2, NVIDIA_TF32_OVERRIDE=0, -c 4096. --n-cpu-moe 37 did not fit the MTP context's compute buffer at -c 4096. Shards preheated, two warm-ups discarded, greedy, cache_prompt off, reasoning_effort low through chat_template_kwargs.
| model | GLM-5.3-Flash-UD-Q4_K_XL-00001-of-00006.gguf |
| quantisation | UD-Q4_K_XL |
| size | 321B params · 23B active · 199.7 GB · MoE 288/8 |
| engine | llama-server b11036 |
| host | linux |
| gpus | NVIDIA GeForce RTX 3090 / NVIDIA RTX A6000 |
| streams | 1 |
| workload | 497 in / 2000 out · 283 thinking · cache 0% |
| context | 4096 window · 1 slot |
| config | fa off · ngl 999 · offload partial |
| machine | 174.5 of 550 W |
| prompt set | not in a comparison set |
| recorded | 2026-10-01T18:53:02Z |
| toktape | v0.6.0 |
Details
The transcript, the card as text, and why each caveat fired — read out of the record in your browser, the same way Replay draws it.
recorded. The card that comes with this record spells each one out.Page views are counted with Cloudflare Web Analytics: no cookies, no fingerprinting. The toktape binary itself sends nothing anywhere.